Your Robots.txt Says Allowed. Your Firewall Says Blocked.
A site owner checks Google Search Console and everything looks fine. Crawl stats are healthy, indexation is stable, rankings haven't moved. Then a customer mentions they asked ChatGPT about the business and got told it has no information on it, even though the site has been live for years with a full product catalog and an active blog.
The site isn't broken. It's invisible to a whole category of crawler that Search Console was never built to report on.
The Audit Which AI Crawlers Can Actually Access Your Site prompt exists for exactly this gap: it turns a robots.txt file and a couple of configuration questions into a clear table of which AI crawlers can reach the site right now, and what to change if the answer is wrong.
A second population of crawlers
For years, "crawler" meant Googlebot and Bingbot, bots that index a page so a human can click through from a results list later. Site owners tuned robots.txt around that one relationship: block the admin folder, block duplicate parameter pages, let everything else through.
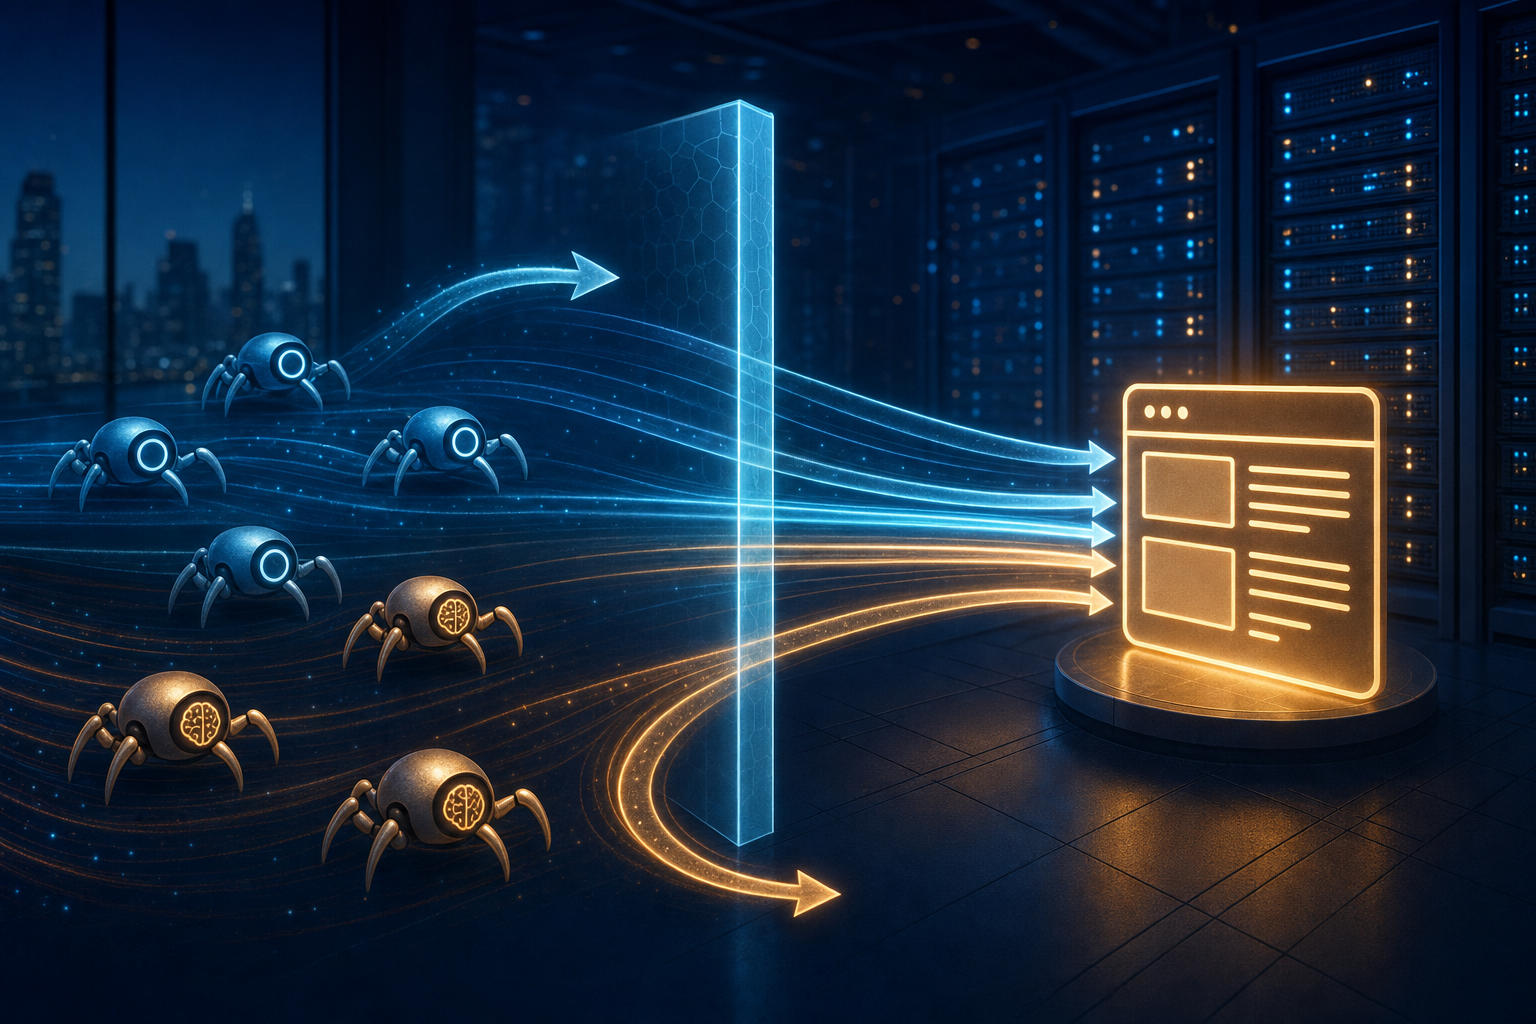
A different set of crawlers now visits the same sites for a different reason. GPTBot, ClaudeBot, PerplexityBot, and OAI-SearchBot aren't indexing pages for a results list. They're reading content that AI assistants draw on when someone asks a question in a chat interface. No click has to happen for that visit to matter. If a competitor's page is readable by these bots and a site's isn't, the competitor is the one getting recommended.
A worked example
Run the prompt against a mid-size B2B company's real robots.txt file, with the CDN question answered honestly and a stated goal of maximizing AI visibility. The output comes back as a status table: Googlebot and Bingbot allowed, GPTBot and ClaudeBot allowed by robots.txt itself, but the site sits behind Cloudflare with its "block AI bots" toggle switched on from 2024, so the real answer is blocked. OAI-SearchBot, the crawler behind ChatGPT's live web citations, is caught by that same toggle.
The fix isn't a content problem or a strategy problem. It's one dashboard setting from 2024 that never got rechecked once AI visibility became a goal instead of a scraping worry. The prompt catches the mismatch because it asks about the network layer as well as the robots.txt file, which is the part a file-only check would miss.
Where the real value is
The setting a business actually wants here isn't universal. A publisher whose revenue depends on direct page visits has a real reason to block a bot that summarizes content without sending a reader back. A B2B company whose buyers increasingly start research inside a chat interface wants the opposite: getting cited by an AI assistant is a new channel, not a threat. That's why the prompt asks for a stated business goal before recommending a setting, rather than treating every crawler as good or bad by default.
The time saved is in the diagnosis, not the fix itself. Editing a robots.txt line takes a minute. Realizing a firewall setting from two years ago is overriding it without any warning takes most audits far longer to find, if they ever check at all.
How to use it
- Pull the site's current robots.txt content and note whether it sits behind a CDN or firewall service like Cloudflare.
- Decide the actual goal: maximize AI visibility, restrict AI training use, or a mixed setting by bot.
- Run the prompt with those three inputs and apply the exact robots.txt lines it returns, then check the flagged network-level setting separately.
Any SEO consultant or in-house marketer working with a site that hasn't touched its AI-crawler settings since before this was a live business concern should run this one today. Grab the full prompt here and check both layers, the file and the firewall, before assuming either one is telling the whole story.